◀︎ // Home
Section 07 // What This Means for Defenders
Adopt the Straiker STAR Framework
Bottom line for leadership
Five controls break the chain across every agent type, and the decisive one is runtime monitoring (agent-on-agent). Guardrails are the baseline; runtime is the catch.
Do this: inventory every agent you run, test them against these attacks, then defend at runtime.
The framework's operational value is showing defenders where attacks happen and which control breaks each step. Four cross-cutting controls run through every agent type in this report, plus a fifth that catches what the others miss.

Five controls across every agent type
// 01
Treat external content as untrusted instruction
READMEs, emails, invites, shared docs, internal RAG sources, and tool descriptions. This closes the LAVA delivery channel.
// 02
Narrow permissions to task scope
Least privilege on the tool registry, OAuth scopes, and per-tool authorization. Shrinks the blast radius before anything fails.
// 03
Approve irreversible actions
Destructive commands, external sharing, mailbox rules, and cross-system transfers gated by a human.
// 04
Monitor context against action at runtime
Watch what the agent reads against what it does, and flag the moment the two diverge from the user's intent.
05 // The 5th Control
Agent-on-agent runtime security
The one this report returns to most. An agent watching another agent's context catches novel patterns the model itself cannot recognize. AI agents need an AI agent to secure them.
Start by seeing what you run
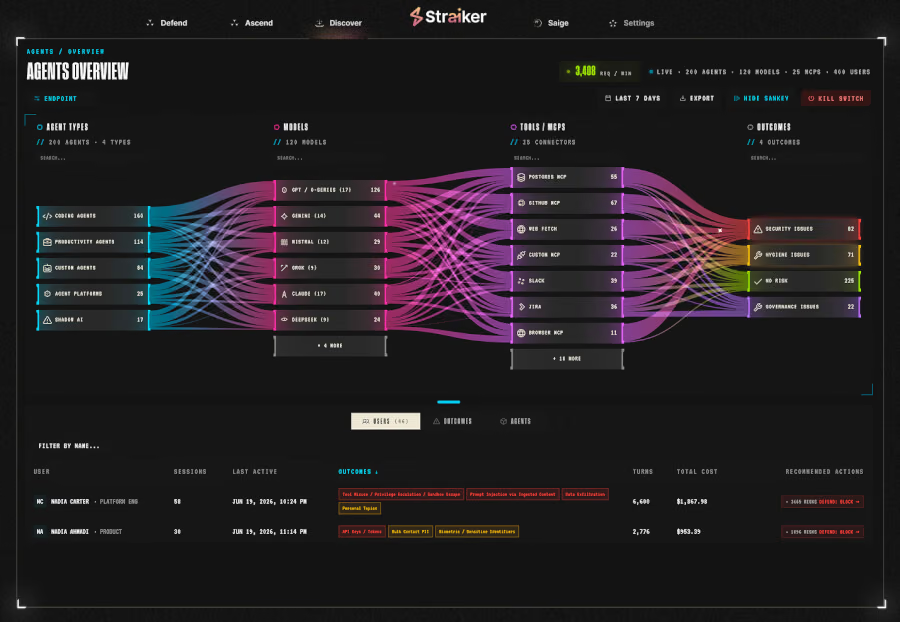
Adopting the STAR Framework starts with knowing what agents already operate inside your organization. Discover AI inventories every AI agent, MCP server, and connected model across the enterprise, and grades each against the framework's four layers and three agent types.
98.1%
detection accuracy across all threat categories
99%
detection on coding agents at runtime
0.7%
false-positive rate, near-zero noise
<300ms
added latency

The fastest way to know your exposure is to test for it. Straiker runs continuous AI adversarial testing — the same classes of attack documented in this report — against your live agents. In Gartner's Reference Architecture Brief: Offensive AI Security Testing, Straiker was positioned among the commercial vendors with distinct AI-ST capabilities, and Ascend AI was named a winner in The Hacker News 2026 awards for red teaming. That is why teams come to Straiker to test agents the way real attackers would, continuously.
Get the Full Report
Read everything here, free. Enter your email and we'll send the full PDF, including the complete defender playbook.
Frequently Asked Questions
How do you defend AI agents against agentic attacks?
Defending AI agents against agentic attacks requires five controls: treat external content as untrusted instructions, limit permissions to the task scope, require human approval for irreversible actions, monitor context against action at runtime, and use agent-on-agent runtime security. Together, these controls help break attacks before they reach their intended outcome.
What is agent-on-agent runtime security?
Agent-on-agent runtime security is a security approach in which one AI agent monitors another agent's context and behavior in real time. It can identify prompt injection and LAVA patterns that the protected model may not recognize. In the Straiker STAR Framework, agent-on-agent security is the fifth control for defending AI agents at runtime.
How does Straiker's platform map to the STAR Framework?
Straiker's three products follow a See-Test-Protect path. Discover AI inventories agents, MCP servers, and models and grades their risk across the framework. Ascend AI continuously red-teams them using adversarial attacks mapped to the framework. Defend AI protects agents at runtime with 98.1% detection accuracy across threat categories, 99% on coding agents, and a 0.7% false-positive rate.